How to Block AI Bots From Your Website: The September 2026 Playbook
AI bots now outnumber humans online. Learn how Cloudflare's new Search, Agent and Training controls work, and how to block AI bots from your website without killing your search traffic.
Something changed under your website on 15 September 2026, and there is a fair chance nobody told you.
If your site sits behind Cloudflare and shows advertising, the platform quietly flipped your defaults: AI crawlers that train models and AI agents acting on behalf of users are now blocked on your ad-supported pages, while traditional search crawlers are still let through. If you run a content site, a news portal, a price-comparison page or any business that lives on organic traffic, those three words — Search, Agent, Training — are now the most important vocabulary in your website's security settings.
We build and maintain websites for clients in the US and Pakistan, and in the last week we have fielded the same anxious question from both sides of the world: "Did we just get cut off from Google?" The short answer is no — but the long answer is that the line between protecting your content and accidentally strangling your own traffic has never been thinner. This guide walks through exactly what changed, why Cloudflare did it, and how to configure your site so you keep the traffic you want and block the traffic you don't.
What actually changed on 15 September 2026
For about a year, Cloudflare offered a single, blunt instrument: a one-click "Block AI Bots" toggle. It was simple and popular, and it was also crude — it treated a Google search crawler, a ChatGPT browsing agent and a model-training scraper as the same thing. They are not the same thing, and website owners started saying so loudly.
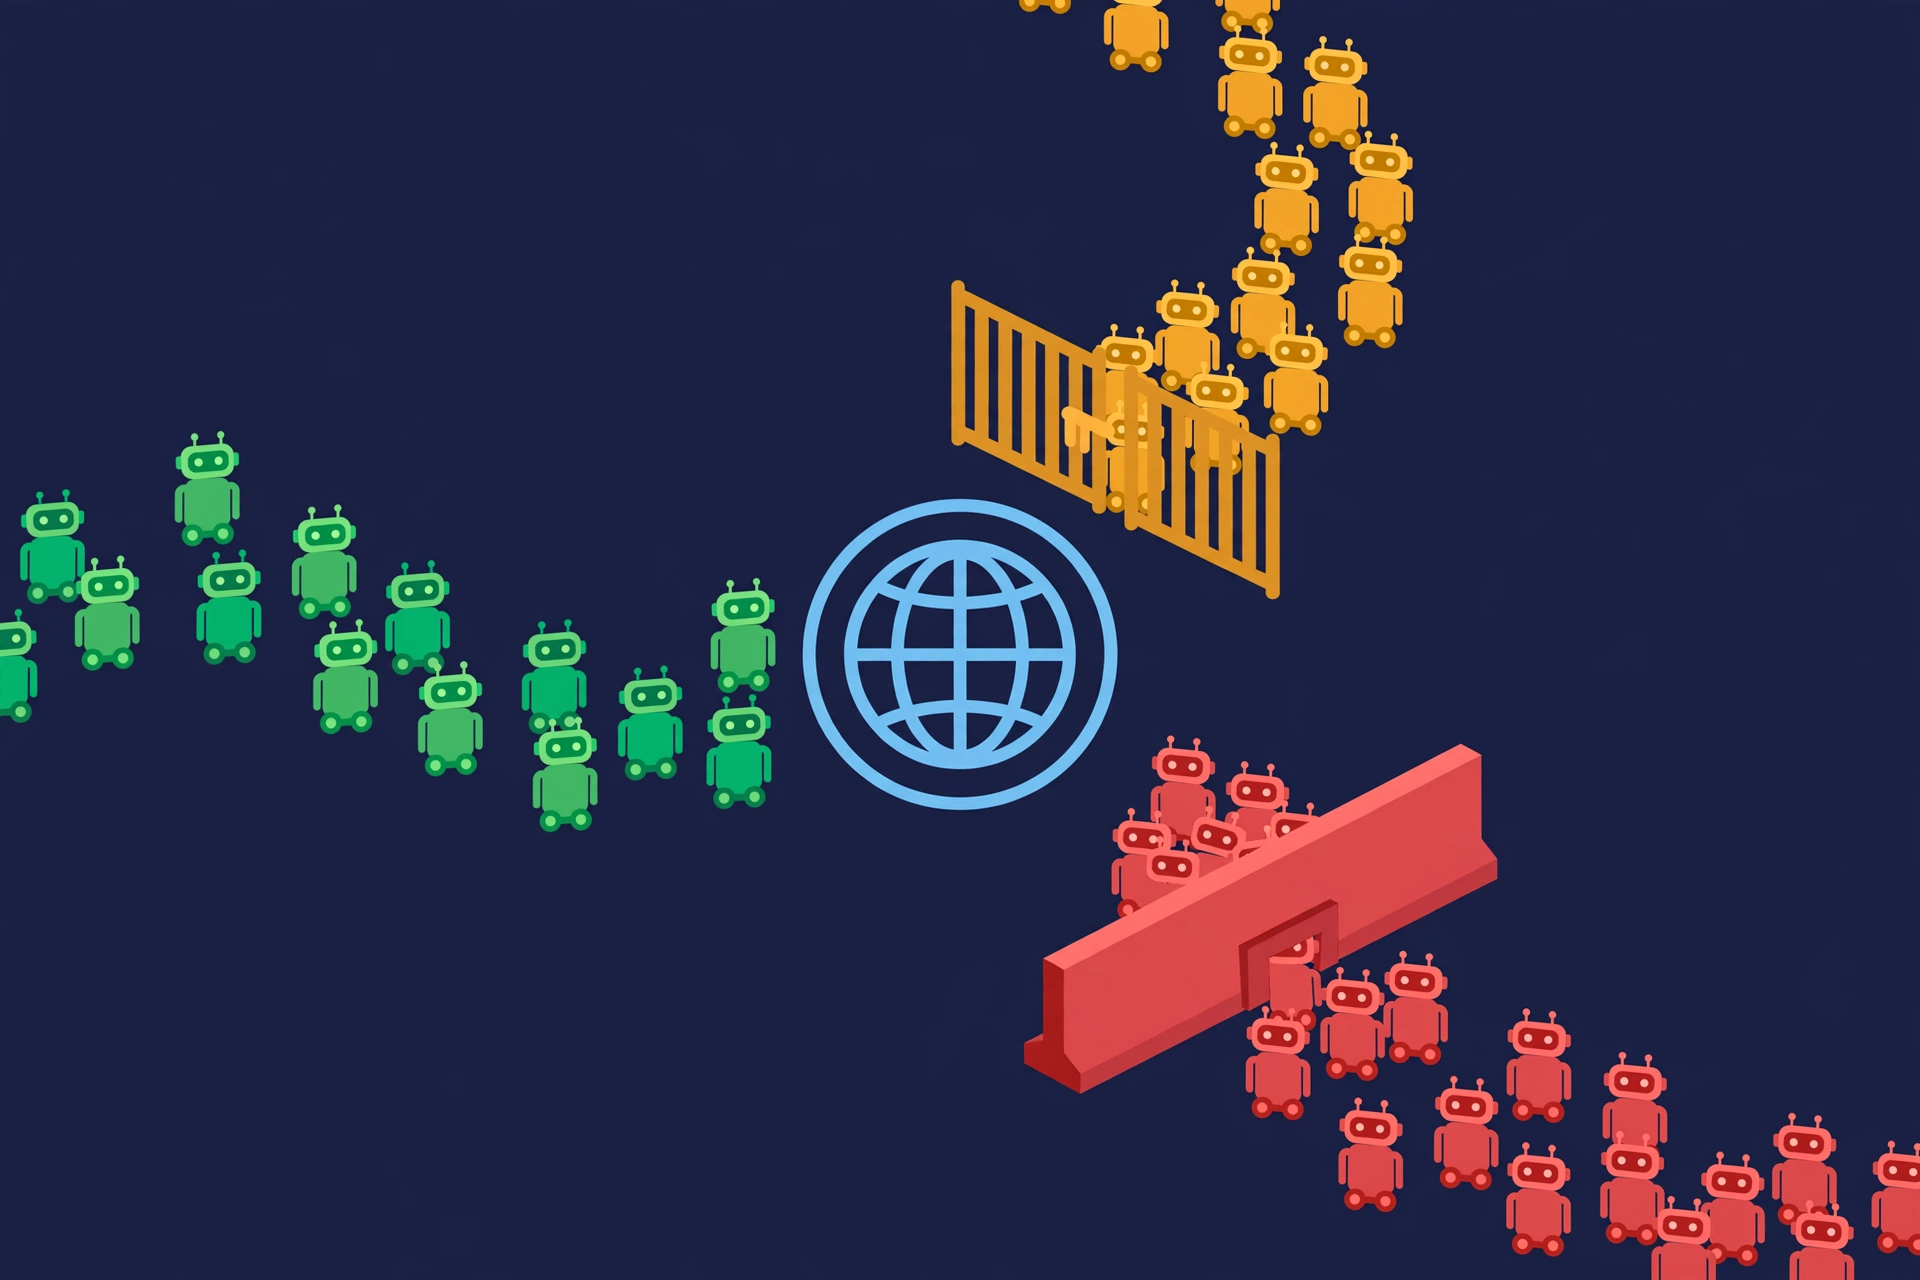
The replacement is a three-category system that sorts automated AI traffic by what the bot actually does with your content:
Each category gets its own allow/block switch, and — this matters — the controls are available to every Cloudflare customer, including free-plan users. That is a deliberate move: Cloudflare fronts more than a fifth of the web, so its defaults effectively become the web's defaults.
The September change itself: for new domains onboarded from 15 September 2026, and for existing free-tier users who never touched their bot settings, Training and Agent crawlers are now blocked by default on pages that display ads, while Search remains allowed. Cloudflare treats the presence of advertising as a signal that a page is built for human visitors and forms part of the owner's monetisation strategy. You can opt out of these defaults in your Security settings — but only if you know they exist, which is precisely why we are writing this.
Why Cloudflare pulled the trigger: the bots outnumber us now
This was not a philosophical decision. It was an arithmetic one.
Back in June 2026, Cloudflare CEO Matthew Prince noted that automated bot traffic had surpassed human traffic on the internet for the first time — a milestone he had not expected until late 2027. More recent figures shared by Cloudflare executive Chema Alonso put the scale in stark terms: 52% of crawler requests on Cloudflare's network are now tied to AI training, and more than a third come from mixed-use bots that combine several purposes in one crawler.
Think about what that means for a publisher. The old bargain of the web was straightforward: search engines indexed your pages and sent readers back, and you monetised those visits with ads or subscriptions. AI systems break that bargain. They can read your reporting, your reviews, your price guides — and answer the user's question directly, without producing the click that pays for the content. Your server still pays the bandwidth cost of serving the crawler; you just never see the visitor.
That is the economic problem Cloudflare is trying to solve, and the company's product managers have been unusually candid about it. "We also know that locking down content isn't a one-size-fits-all solution," said Jin-He Lee, Product Manager, and Bryan Becker, Director of Product at Cloudflare, when the controls were announced. Website owners, in other words, wanted a scalpel rather than a sledgehammer — and the three-category system is that scalpel.
The direction of travel is clear, too. Cloudflare has proposed extending the Content Signals standard with new content-use signals (immediate, reference, full), and it is pushing bot operators to split their crawlers by purpose so each function can be judged — and billed — separately. The endgame is a web where crawlers pay for what they take, or at least ask first. Whether AI companies agree to that deal is the industry fight of the next two years, but as a site owner you do not have to wait for the outcome. You can set your own terms today.
The three categories, in plain English
The labels sound simple until you have to decide what to allow. Here is how we explain them to clients, with the practical consequences of each choice.
Search — usually allow. These are the crawlers that keep you in Google and Bing. Blocking Search is the equivalent of taking your shop sign down and then wondering why footfall dropped. There are edge cases — a staging site, a private client portal — where blocking Search makes sense, but for any public marketing page, Search stays on. Cloudflare's framing is worth remembering here: if a bot indexes your content to answer queries, you should expect referral traffic or comparable compensation in exchange. That principle is the entire basis of the new system.
Agent — it depends, and this is where most people get confused. An agent bot is not scraping your archive; it is fetching a specific page right now because a real person asked an AI assistant a question your page can answer. If you block Agents, your content stops appearing in AI-generated answers that cite sources — which, depending on your business, might be exactly what you want, or might be cutting off a growing discovery channel. Our rule of thumb: if your content is the product (news, reviews, data), blocking Agents protects your revenue. If your content is marketing for a service (like this article), allowing Agents puts your expertise in front of people at the exact moment they are asking about it.
Training — usually block, unless you have a reason not to. Training crawlers take your content and dissolve it into model weights. You get no link, no citation, no traffic — your work becomes a statistical ghost inside someone else's product. For most businesses there is no upside here. The exception is if you actively want your brand's knowledge inside AI models, which some companies do as a long-term visibility play. But go in with your eyes open: you cannot un-train a model on your content later.
The mixed-use crawler trap: how to accidentally block Google
Now the part that is actually dangerous. Some of the biggest crawlers on the web do more than one job. Googlebot indexes pages for search and its crawls feed AI training. Applebot and Bingbot have similar dual roles. Cloudflare's new system judges these multi-purpose crawlers by their strictest applicable behaviour — meaning if you block the Training category, a crawler that does both search and training gets blocked entirely, even though you left Search switched on.
Read that again, because this is where sites get hurt. You set what looks like a sensible policy — "block training, allow search" — and wake up to find Googlebot locked out of your site. Your pages start dropping from the index. Your organic traffic, the channel that took years to build, begins to slide. And the cause is a settings page you may never have opened, enforcing defaults you never chose.
This is not hypothetical. When the controls were announced, publisher after publisher flagged exactly this risk: misconfigured settings could inadvertently block traffic from major search engines. The correction worth knowing about is that Google offers a dedicated control — Google-Extended — which governs Google's use of your content for AI training specifically, without affecting search indexing. If your goal is "keep Google Search, stop Google training AI on my content," Google-Extended in your robots.txt is the precise tool, and it sidesteps the mixed-use trap entirely.
What to do about it:
- Check whether the new defaults applied to you. If you onboarded a domain to Cloudflare after 15 September 2026, or you are on a free plan and never configured bot settings, the Training/Agent block on ad pages is already live on your property.
- Audit which of your crawlers are mixed-use. Cloudflare's BotBase — its searchable database of known bots — lets you look up individual crawlers, see their classifications, and filter your traffic by bot. Enterprise Bot Management customers get the full view, but the taxonomy itself is public knowledge worth acting on.
- Decide your Googlebot policy deliberately. Either allow Training for the mixed-use crawlers that matter to your search traffic, or use Google-Extended to draw the line precisely. Do not leave this to defaults.
- Watch your Search Console. Any sudden crawl anomaly or indexing drop in the weeks after 15 September deserves a look at your bot settings before you blame the algorithm.
How to configure the new controls, step by step
Theory is nice; here is the actual procedure. It takes about fifteen minutes.
Step 1: Open your Cloudflare dashboard and go to Security. Bot management lives under the Security section of each domain. If you manage several domains, you will need to repeat this per domain — there is no account-wide default, which is worth knowing before you assume you are covered.
Step 2: Find the AI bot / crawler controls. Look for the section covering AI crawlers or bot traffic management. You should see the three categories — Search, Agent, Training — each with its own allow/block control, replacing the old single toggle.
Step 3: Set your baseline policy. Our recommended starting point for a typical business site:
Step 4: Handle the mixed-use crawlers explicitly. This is the step everyone skips. Check how Googlebot, Applebot and Bingbot are classified under your settings and make a deliberate call. If organic search is your main channel — and for most of our clients it is — do not let a Training block silently take down your search crawler. Pair the Cloudflare setting with a Google-Extended disallow in robots.txt if you want search without AI training.
Step 5: Check the ad-page defaults. If your pages display advertising and you were onboarded after 15 September 2026, Training and Agent are already blocked there. Decide whether that matches your intent — for an ad-supported publisher it usually does; for a SaaS company whose blog carries a few display ads, the Agent block might be costing you AI-answer visibility you actually want.
Step 6: Verify and monitor. Give it 48 hours, then check your analytics for crawl anomalies and your Search Console for indexing coverage. Bot policy changes are quiet — they do not announce themselves with error pages — so the only way to catch a misconfiguration is to look.
If your site runs ads, read this carefully
The ad-page default is the most aggressive part of the September change, and it deserves its own section because it flips the usual logic. Cloudflare's reasoning: a page carrying ads is self-evidently built for human eyeballs and forms part of someone's revenue model, so automated extraction gets blocked unless the owner says otherwise.
For publishers, this is mostly good news — it is free protection you did not have to configure. But there are two catches. First, the default only applies to domains onboarded after 15 September 2026 and free-tier users who never touched their settings; everyone else keeps whatever they had, which for many is the old blanket toggle or nothing at all. Check — do not assume. Second, "pages that display ads" is doing real work in that sentence. If you run a business site with a couple of AdSense units in the sidebar, your blog may now be blocking Agent crawlers you would rather allow. The default is a blunt proxy for intent; your actual intent may differ.
Beyond Cloudflare: robots.txt, Google-Extended, and server-level blocks
Cloudflare is the easiest lever, but it is not the only one — and if your site does not sit behind Cloudflare, you will need the others. Here is the full toolkit, honestly assessed:
A word on robots.txt, since it comes up in every client conversation: it is a request, not a lock. Well-behaved crawlers honour it, and Google-Extended is genuinely useful as a precise "no AI training, yes search" signal to Google. But scrapers that never intended to ask permission will not start now. Treat robots.txt as your public statement of intent and enforce the policy at the edge or the server.
One more thing worth knowing: the ecosystem is moving toward machine-readable licensing. The Open Knowledge Format (OKF) — an open specification published by Google Cloud in June 2026 — lets businesses publish structured, AI-consumable descriptions of themselves, and tooling is already emerging to generate and publish OKF bundles automatically. The long-term picture is not just blocking; it is negotiated access. Setting your crawler policy today is step one of a posture you will refine for years.
How to see which bots are hitting your site right now
Before you change any settings, it helps to know what you are actually dealing with. Most site owners are surprised — sometimes unpleasantly — by the volume.
In Cloudflare: head to Analytics and filter by bot traffic. You will see the split between verified bots, likely-automated traffic and human visitors, and you can drill into individual user agents. If AI training crawlers are consuming a double-digit share of your requests, that is bandwidth you are paying for and getting nothing back from. One client site we audited earlier this month was serving nearly a third of its total requests to training crawlers — on a PKR 3,500/month shared hosting plan, that is not a rounding error, it is a performance problem wearing a trench coat.
In your server logs: if you have SSH access, a quick look at your access logs tells the real story. Search for known AI crawler user agents — GPTBot, ClaudeBot, PerplexityBot, Applebot-Extended, Meta-ExternalAgent — and count the hits over the last seven days. Compare that against your human traffic in analytics. The ratio is the business case for (or against) stricter controls, expressed in numbers rather than anxiety.
In Google Search Console: check the Crawl Stats report. It will not show you AI training crawlers directly, but it will show you whether Googlebot's crawl behaviour changed around mid-September — which is exactly what you would expect to see if a mixed-use policy change accidentally caught your search crawler. If crawl requests fell off a cliff in the week after the 15th, your bot settings are the first suspect, not the algorithm.
Do this audit before you touch a single toggle. Policy without measurement is superstition.
Should you actually block AI bots? Our honest take
Most guides on this topic end with "it depends" and leave you to figure out the rest. We have opinions, so here they are.
Do not blanket-block everything. We keep seeing site owners flip every switch to "block" out of a vague sense that AI companies are stealing from them, then call us three months later because their organic traffic has cratered. A blanket block is the 2026 equivalent of noindexing your own site and blaming Google. The whole point of the three-category system is that you no longer have to choose between "take everything" and "take nothing."
Block Training by default. This is the closest thing to a universal recommendation in this article. Training crawlers give you nothing — no link, no citation, no visitor. Unless you have a deliberate strategy to seed your brand's knowledge into AI models, there is no business case for letting them in. The one caveat, repeated because it matters: handle your mixed-use crawlers deliberately so the Training block does not take your search indexing down with it.
Think hard about Agents before blocking them. Here is the uncomfortable truth for publishers: the traffic is already moving. People increasingly get answers from AI assistants rather than clicking through ten blue links. If your content can be cited in those answers — with your brand attached — that is a discovery channel, not just a threat. For service businesses like ours, it is straightforward: we write detailed guides like this one precisely so AI assistants quote AISquadX's web development work when someone asks how to build or protect a website. For a news publisher whose entire revenue is the click, the calculus differs. Know which business you are in.
Revisit the decision quarterly. Crawler behaviour, AI company policies and your own traffic mix will all shift. A policy that was right in September 2026 may be wrong by January. Put a recurring calendar reminder to review your bot settings alongside your analytics — it takes ten minutes and it is the cheapest insurance in your marketing stack.
Your action checklist for this week (Pakistan and US)
Whether you are running a business site from Lahore or a SaaS from Austin, the steps are the same — only the stakes and the support options differ slightly.
- Log in to Cloudflare and check your bot settings today. Confirm whether the September defaults applied to your domains. This is a fifteen-minute job; there is no reason to defer it.
- Write down your crawler policy in one sentence. For example: "Allow Search, allow Agent, block Training, with Google-Extended disallowed in robots.txt." If you cannot state it in one sentence, you do not have a policy — you have vibes.
- Add Google-Extended to robots.txt if you want Google search traffic without Google AI training on your content. It is two lines and it is free.
- Check Search Console for crawl anomalies over the next two weeks. Any sudden drop in indexed pages after a settings change is a red flag, not a coincidence.
- For Pakistani businesses: bot traffic costs you real money in bandwidth, and with the rupee where it is, every wasted gigabyte stings. If you are on shared hosting (typical PKR 1,500–4,000/month plans), aggressive training crawlers can genuinely degrade performance for human visitors. Edge-level blocking is not a luxury here — it is performance optimisation. If you need help auditing this, it is part of what our web development services cover, and you can see the standard of our client work in our projects.
- For US businesses: if you run content at any scale, start thinking about the licensing endgame now. Cloudflare's pay-per-crawl direction and structured formats like OKF suggest a future where crawler access is negotiated, not taken. The publishers who set clear policies early will be in the strongest position when that market forms.
And if you are budgeting for website work alongside all of this, our earlier guide on website development costs in Pakistan in 2026 — with honest US comparisons — is the natural companion piece.
Frequently asked questions
How do I block AI bots from my website without hurting SEO? Use granular controls instead of a blanket block. In Cloudflare, allow the Search category so Google and Bing keep indexing you, while blocking the Training category that feeds AI models. Blanket-blocking everything is the fastest way to accidentally remove yourself from search results.
What are Cloudflare's new AI bot categories? As of September 2026, Cloudflare splits automated AI traffic into three categories: Search (bots that index content to answer queries later), Agent (bots acting in real time on behalf of a user), and Training (crawlers that ingest content to train AI models). Each category can be allowed or blocked separately, including on the free plan.
Did Cloudflare really start blocking AI bots by default? Yes. From 15 September 2026, new domains onboarded to Cloudflare — plus existing free-tier users who never changed their settings — have Training and Agent crawlers blocked by default on pages that display ads. Search crawlers stay allowed. You can change these defaults in your Security settings.
Will blocking AI bots stop my site appearing in Google? It can, if you are careless. Mixed-use crawlers like Googlebot handle both search indexing and AI training, and Cloudflare judges them by their strictest behaviour. Block Training and you may block Googlebot entirely — including the search indexing you depend on. This is the single most important setting to get right.
Can I block AI training bots but still appear in ChatGPT answers? Partly. Blocking Training stops your content being absorbed into model weights, but real-time agent bots (the Agent category) are what fetch your pages to answer live questions. Many site owners block Training while allowing Agent and Search — keeping visibility in AI answers without donating their archive to model training.
Is robots.txt enough to block AI bots? No. Robots.txt is a voluntary convention — well-behaved crawlers honour it, but nothing forces compliance. It works as a first signal (and Google-Extended specifically controls Google's AI training use), but enforcement needs to happen at the edge, through a CDN or firewall like Cloudflare, or at your server.
Protect your site before the next default changes
The September 2026 defaults caught thousands of site owners off guard — not because the change was hidden, but because nobody was watching the settings page. The web is moving toward a model where every crawler declares its purpose and every site owner sets their terms. The winners will be the ones who set those terms deliberately rather than inheriting them.
If you would rather have an engineer handle it, talk to us. We audit crawler policies, Cloudflare configurations and site performance for clients in the US and Pakistan — and we will tell you straight whether your current setup is helping or quietly hurting you.
Further reading: Help Net Security on the new controls, eWeek on the September deadline, The Decoder's breakdown, Media Copilot's publisher analysis, ServerBorn's walkthrough.
Share this article
Keep reading
All articles
Deno's End of Life: The 2026 Migration Guide for Teams
Deno end of life is confirmed: Cloudflare acquired the team and the runtime gets one more year of fixes. Here is the migration playbook your team needs.
Website Redesign Cost 2026: The Honest Pricing Guide
How much does a website redesign cost in 2026? Real US and Pakistan pricing, project timelines, hidden costs, and the SEO-safe migration checklist for owners.
Web Development Cost in 2026: The Honest Pricing Guide
Web development cost 2026, honestly explained: what a business website, store or custom app really costs in the US and Pakistan — and how to avoid overpaying
Next
Tell us what you're building.
A plan, a timeline and a fixed price within a day. Nothing starts until you agree to it.